Serhii Ulman
CEO & Co-founder
High-Load System Development & Scalable Backend Engineering
We help you find out before your users do — and fix it before it costs you. Binerals engineers production systems that handle millions of users, thousands of concurrent sessions, and payment volumes where every second of downtime means lost revenue.
We'll review your system and tell you exactly what will break first under 10x load — and what to fix. Delivered within 5 business days.
The symptoms of under-engineered systems tend to follow a predictable pattern. If any of these sound familiar, your platform may already be showing signs of structural load problems:
Database queries that worked fine at 10,000 users start crawling at 500,000 - often because indexing strategy wasn't designed with volume in mind
Peak traffic events — product launches, campaigns, viral moments - cause slowdowns or outages that damage user trust and revenue
Infrastructure costs grow faster than user numbers because teams resort to vertical scaling instead of architectural solutions
We've engineered and optimized systems operating at 1M+ daily active users. This includes full-stack work across backend logic, data layer, caching architecture, and cloud infrastructure. We understand how load distribution changes at scale — where bottlenecks form, how to prevent them, and how to design systems that absorb traffic spikes without degrading. Our engineers have worked on platforms where a 5% increase in latency translates directly to user drop-off. We treat performance as a product requirement, not an afterthought.
Payment flows demand zero tolerance for errors. A missed transaction, a duplicate charge, or a race condition at checkout isn't a bug — it's a financial and reputational risk. We build transaction processing systems with high throughput, guaranteed data integrity, idempotency guarantees, and retry logic that handles partial failures gracefully. Our payment system work spans e-commerce platforms, subscription billing, digital marketplace payouts, and high-volume communication platforms where billing is tied to usage at scale. We design these systems so they remain correct under concurrent load — not just fast.
One codebase. One platform. Hundreds — or even thousands — of distinct brands with overlapping or isolated user groups, separate domains, custom configurations, and independent billing. This is a complex architectural challenge that requires careful data isolation, flexible configuration management, and infrastructure that doesn't let one brand's traffic affect another's performance. We've built and maintained multi-site architectures at scale — up to 500 brands on a single platform — reducing operational overhead dramatically compared to maintaining separate codebases per brand. The result is faster deployment, consistent quality, and far lower infrastructure cost per brand.
Systems that grow with the load — automatically. We deploy Kubernetes-based infrastructure with horizontal pod autoscaling, so your platform handles 10x traffic spikes without manual intervention and without paying for peak capacity 24/7. Auto-scaling isn't just about adding servers. It requires thoughtful service design — stateless services, proper health checks, fast startup times, and queue-based workload distribution. We design for these properties from the beginning so that scaling is genuinely elastic, not just theoretical.
Flash sale and campaign traffic handling — engineered for 50x baseline spikes without degradation
Inventory consistency under concurrent purchases — no oversells, no duplicate orders
Catalog at scale - millions of SKUs with filtered search, personalized pricing, and real-time stock
Order pipeline reliability - asynchronous processing with guaranteed delivery and audit trail
Session and cart management - high read/write concurrency with Redis-backed state
Load-tested payment flows that hold up when everyone checks out at once

Deep Dive
See how we approach the full e-commerce engineering stack — from flash sale architecture to multi-warehouse inventory and checkout reliability under concurrent load.
Before writing a line of code, we map the system and find where it breaks under load. Most performance problems have a clear root cause — a missing index, a synchronous operation that should be async, a service that doesn't isolate failure. For existing platforms, we treat it as a structured diagnostic — combining code review, query analysis, and load profiling to build an honest picture of where the system stands.
The database is where most high-load problems live. We work across MySQL, PostgreSQL, and MongoDB: query analysis and rewriting, index design for actual access patterns, table partitioning, and replication strategy for read-heavy workloads. Master-replica architectures with read balancing can dramatically reduce load on the primary database. We've cut query times from seconds to milliseconds through indexing and query rewriting alone.
We design cache invalidation strategies, TTL policies, and warming procedures that work correctly under concurrent writes, flash sales, and data migration. We implement Redis and Memcached-based caching layers designed around actual read patterns — not as afterthoughts — ensuring cache hit rates that meaningfully reduce database load at scale.
Synchronous processing is a scalability ceiling. We identify operations that can be decoupled from the request lifecycle and move them to reliable async pipelines — using RabbitMQ, Kafka, or SQS depending on throughput and ordering requirements. Queue-based architecture also improves resilience: when a downstream service slows, work accumulates in the queue rather than crashing the entire system.
We provision and manage cloud infrastructure on AWS, GCP, and Azure with infrastructure-as-code. Kubernetes is our primary orchestration platform for containerized workloads. We configure horizontal pod autoscaling based on real traffic metrics and implement cost controls so that elasticity doesn't turn into runaway spend at scale.
Every major change goes through realistic load testing — using k6, Locust, or JMeter — simulating actual traffic patterns including peak scenarios, gradual ramp-up, and flash spike conditions. We declare victory only when the system holds up to the conditions it was designed for. Load test results are shared in full, including latency percentile distributions and failure thresholds.
Free · No commitment · 5 business days
We'll map your architecture, identify the top 3 bottlenecks, and tell you exactly what breaks first under 10× load.
We start by understanding your system: what it does, how it's built, what problems you're experiencing or anticipating. For existing systems, we combine code review, database profiling, and infrastructure audit. Output: a clear picture of where you are and what needs to change.
Not everything needs to be fixed at once. We prioritize improvements by impact — focusing first on changes that will deliver the most meaningful performance and reliability gains. You get a roadmap with clear tradeoffs, not an infinite list of recommendations.
Before any major change goes to production, we run load tests that simulate real traffic patterns — including peak scenarios. We don't declare victory until the system performs correctly under the conditions it was designed for.
We work as an extension of your team, not as an external vendor. Our engineers join your communication channels, attend planning sessions, and take ownership of the systems they build. No handoff documents — we stay involved until the work is proven in production.
Performance improvements are only sustainable if you can see when they degrade. We set up instrumentation, dashboards, and alerting so your team can observe system behavior at scale — and catch problems before users do.
CEO & Co-founder
CTO & CFO
Chief Delivery Officer
Brand & Growth
Real incidents. Anonymised. What happened, why it happened, and how we fixed it.
Expect only real cases and solutions tested in practice. We share real experience that helps startups and businesses grow faster.
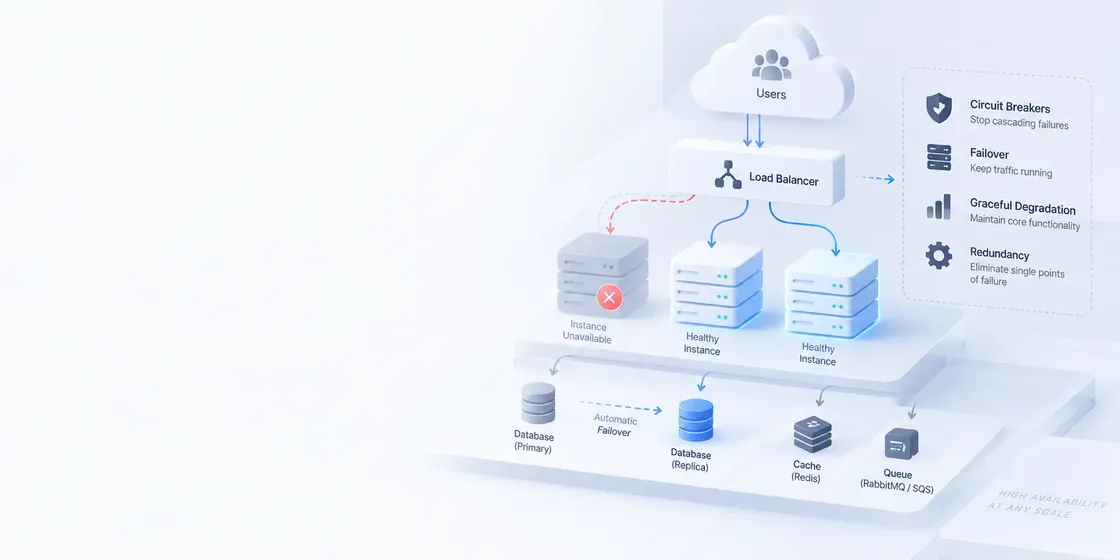
High-load systems rarely fail because every component breaks at once. Downtime usually begins with one overloaded database, unavailable service, failed node, slow dependency, or network problem that spreads through the architecture. Fault tolerance is the discipline of preventing that local failure from becoming a system-wide outage.
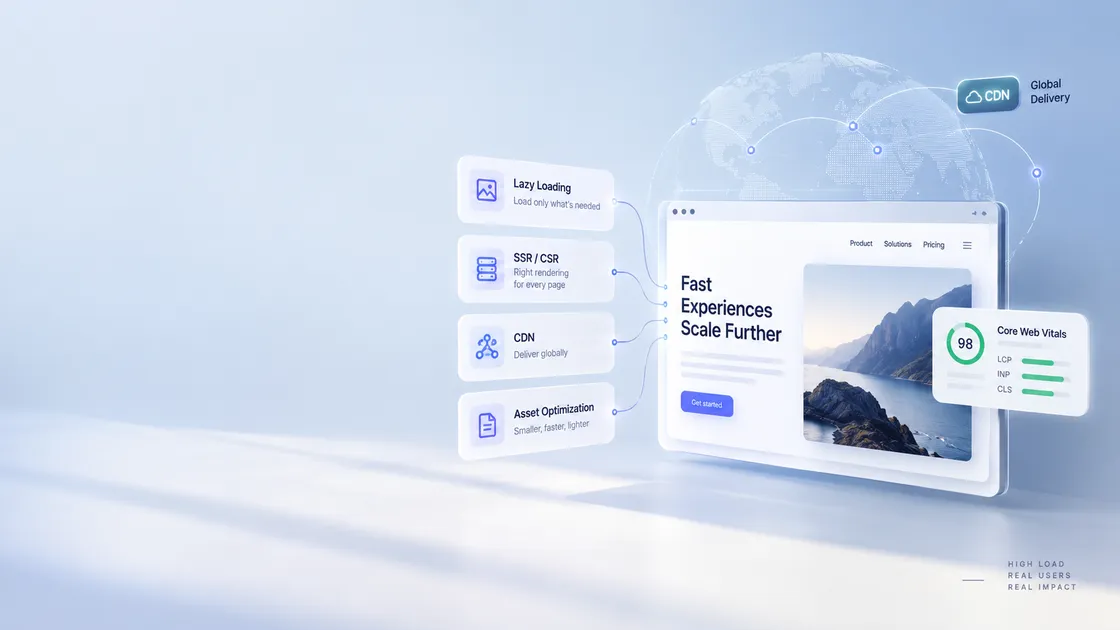
High-load engineering does not end when the backend responds quickly. At scale, rendering strategy, JavaScript execution, images, third-party scripts, caching, and content delivery can become just as important as APIs and databases.
A system capable of processing thousands of requests per second can still feel slow to every person using it.
A digital transformation project usually starts with a clear business case and ends, months later, with a system nobody fully trusts and a budget that's already gone. The pattern is familiar: a rushed vendor selection, a scope that grows mid-build, an architecture chosen for the demo rather than for the next five years of growth.
Your database is burning. Every second, thousands of requests hammer the same dataset. You add Redis. Requests drop 10x. Then a deploy happens, and suddenly your cache serves stale data to customers. Welcome to the real world of caching at scale.
Caching isn't a silver bullet - it's a series of careful trade-offs. This article breaks down the strategies that actually work, how Redis and CDNs fit together, and most importantly: how to invalidate cache without melting your infrastructure.
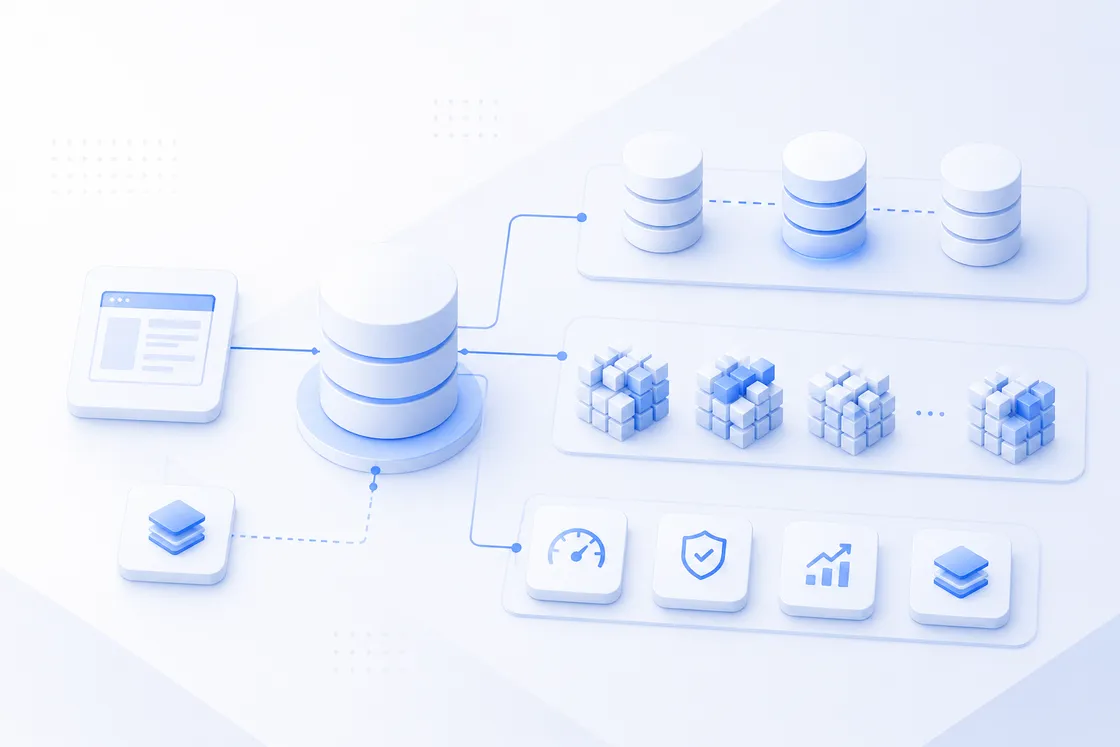
In high load systems, the database is not just a storage layer. It is the primary constraint that defines system performance, latency, and scalability boundaries.
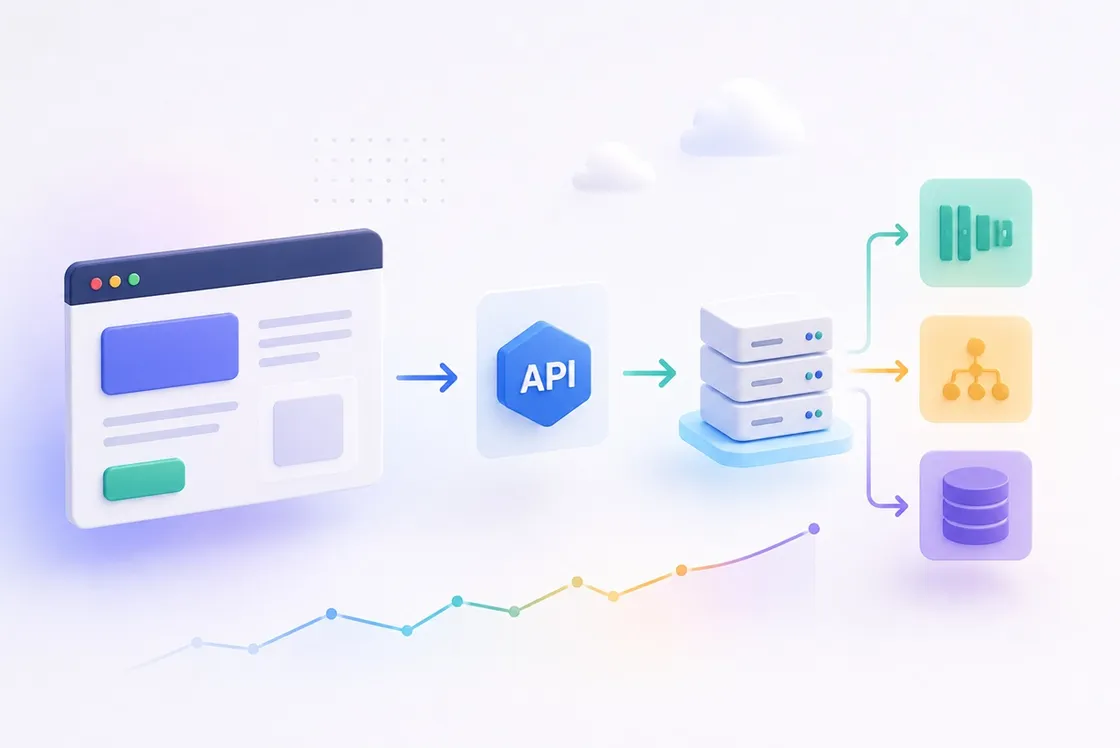
Modern applications are expected to support millions of users while maintaining high performance and reliability. Whether it is a SaaS platform, marketplace, or social product, backend systems must process large volumes of requests without slowing down or failing under pressure.
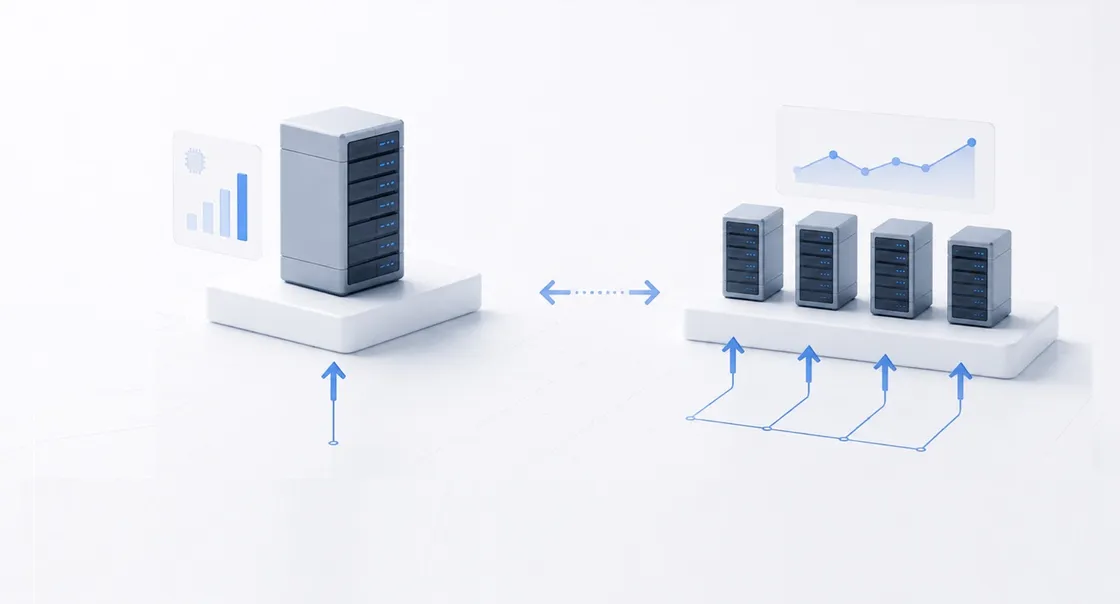
Users searching for “vertical vs horizontal scaling”, “how to scale a web application”, or “how to handle high traffic systems” are typically founders, CTOs, or engineering leads who are facing real performance limits or planning for growth. They want to understand which scaling approach is more cost-effective, when to move from scale up to scale out, and how to avoid architectural mistakes that lead to downtime or unnecessary infrastructure costs.
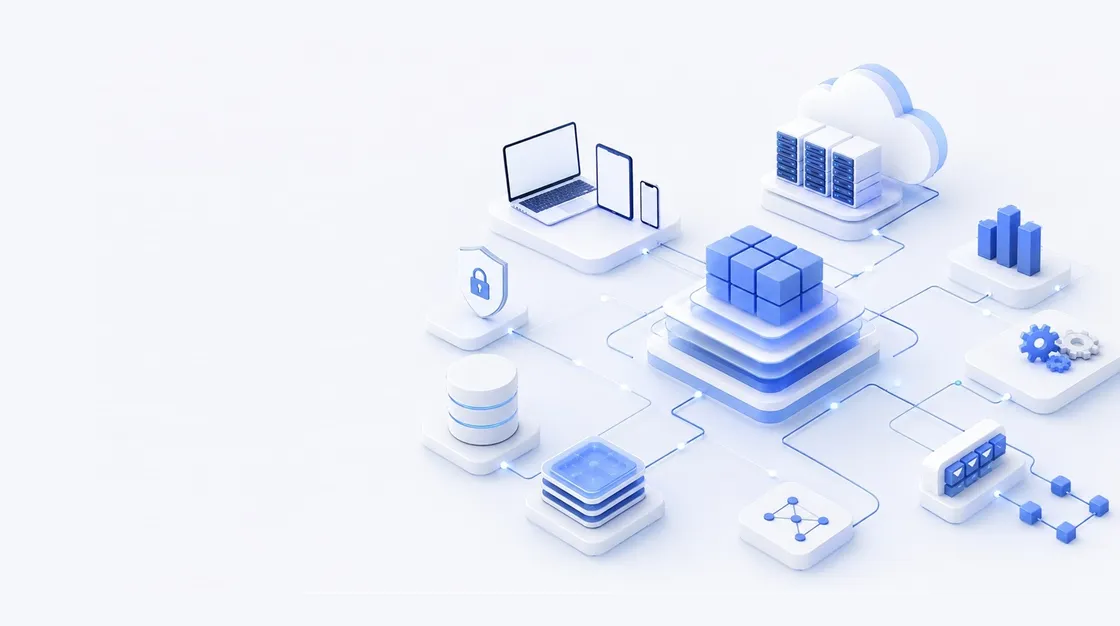
Users searching for “scalable system design”, “scalable architecture patterns”, or “how to handle high traffic systems” are typically product owners, CTOs, and engineering leads evaluating how to evolve an existing system or design a new one that can grow without breaking under real demand.
Users searching for “high load architecture”, “scalable web application architecture”, or “how to handle high traffic systems” are typically decision-makers or tech leads who need to understand how to design systems that will not break under growth, and what architectural choices actually impact scalability, reliability, and long-term cost.
Most products don’t fail because of lack of features - they fail when growth hits and the system cannot keep up. High load is not about traffic numbers. It is about the moment your architecture starts limiting your business.